Ayush Ummadi

Available for full-time data analyst roles

Finding the number is half the job. Knowing what to do with it is the other half.

Data analyst with a master's in computer science and ten projects across Python, SQL, Excel, Tableau and Power BI. Based in Austin, Texas, and open to relocating.

About

Hey, I'm Ayush. Most weekends I'm somewhere outside with a camera, a kayak or a pair of hiking boots. The rest of the week I'm doing a version of the same thing, just with data.

That's more or less how I landed in analytics. I studied computer science, the data classes were the ones I actually looked forward to, and I kept pulling that thread: a machine learning internship forecasting support ticket volume, a stint at NTT DATA keeping data moving cleanly between enterprise systems, then a master's at the University of Georgia.

What stuck is the last mile. Getting to the right number is the easy part. The useful part is saying what the business should do about it on Monday, in plain words nobody needs a dashboard to decode. So every project here ends with a recommendation.

I'm based in Austin and happy to relocate. Wherever the work is, basically.

Ayush Ummadi
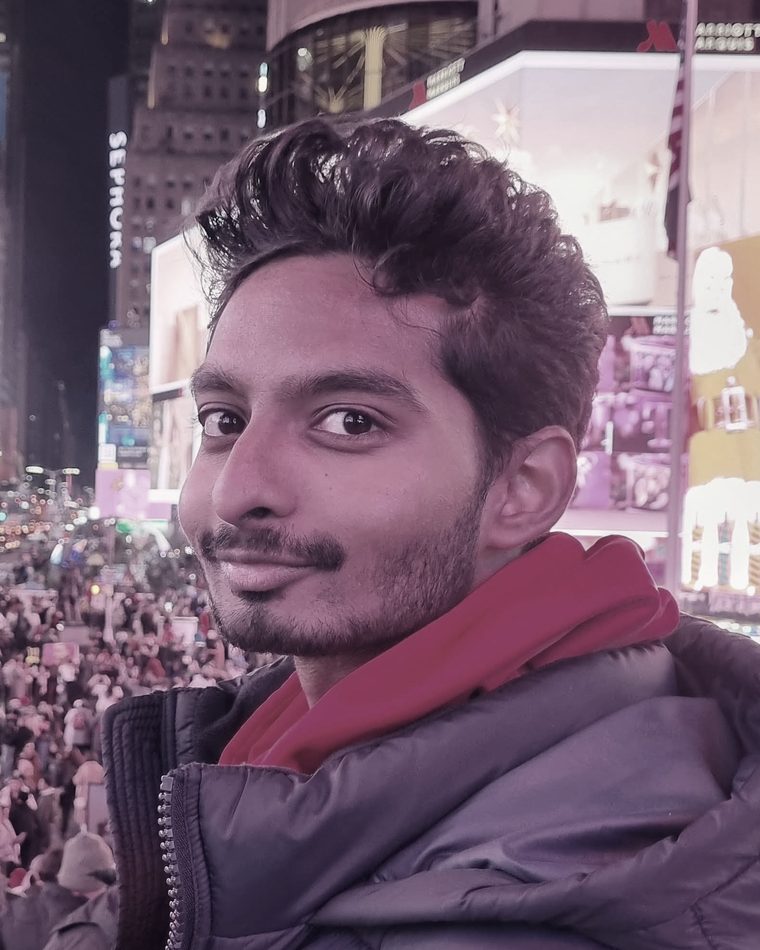
Times Square, December 2024.

How I work

How I work
  1. 1

    Start with the decision

    Before any code, write down what someone should be able to do differently once this is finished.

  2. 2

    Clean it honestly

    Most of the time goes here. Missing values, redundant columns, sensible types, then into a database where SQL can reach it.

  3. 3

    Ask real questions

    A handful of queries aimed at the business question beats forty charts nobody asked for.

  4. 4

    End with a recommendation

    Say what to do, what it rests on, and what the data cannot tell you. That last part matters.

Featured analysis

Customer Shopping Behaviour Analysis

3,900 customer records cleaned in Python, loaded into PostgreSQL, questioned with ten SQL queries, and delivered as a Power BI dashboard, a written report and a stakeholder deck.

The brief

How can a retailer use its shopping data to spot trends, improve customer engagement and sharpen marketing and product strategy?

  • 3,900customers analysed
  • $233Ktotal revenue
  • $59.76average purchase
  • Python, pandas
  • PostgreSQL
  • SQL, 10 queries
  • Power BI
  • Report and deck

Clothing and Accessories bring in 76.5% of the $233K in revenue.

What I'd doKeep both well stocked and prominent, and grow Footwear and Outerwear by bundling them with the two categories people already come for.

Subscribers spend slightly less per order than non-subscribers, $59.49 against $59.87, and 72% of repeat buyers have never subscribed.

What I'd doMake the subscription earn its place with free express shipping or member-only bundles, and aim it at the 2,518 repeat buyers who never signed up.

Spend per order barely moves. Across gender, category, age group, shipping type and subscription status, the average purchase sits between $57 and $61.

What I'd doStop trying to lift the average order through segments and grow basket size instead: bundles, cross-selling, and a free-shipping threshold just above the current average.

One caveat I would say out loud in an interview: this is a snapshot of each customer's latest purchase with no dates attached, so everything above is a relationship rather than a cause. The full report lists the rest.

More projects

More projects

Nine more, grouped by the tool they were built with. Open one for what the data showed and what I would do about it.

SQL2 projects
Sales and Revenue AnalysisThree years of orders for a scale-model vehicle company, in MySQL

2,823 line items across 307 orders, worked through with CTEs and window functions: revenue trends, product lines, customer behaviour and order operations.

November is the highest-revenue month in every year of the data, and Classic Cars alone account for $3.92M of the $10.03M total.

What I'd doPlan stock and staffing around the November peak and protect the Classic Cars line. Sweden's 28% cancellation and dispute rate deserves a look too, with the caveat that only 57 orders sit behind it.

Customer Segmentation, RFM50 customers sorted into value tiers with CTEs, NTILE and reusable views

RFM scoring across 247 transactions, sorting customers into Champions, Loyal, At Risk, New and Lost, then profiling each segment by demographics and product category.

At Risk customers hold the largest revenue pool at $7,830, and they haven't bought in an average of 253 days.

What I'd doSpend the re-engagement budget here first. It's the biggest pot of money sitting closest to the exit, while the Loyal segment is steady enough to leave alone for a quarter.

Tableau1 project
Superstore Sales Dashboard9,994 orders, live on Tableau Public with year, state and category filters

Sales by state on a choropleth, sales against profit over time, discount and profit distributions, and category donuts, covering 2014 to 2017.

Most revenue comes from orders with little or no discount. The heavily discounted tail contributes far less.

What I'd doBefore widening discounts, check what that heavy tail is actually buying. On this data it reads as margin given away rather than volume bought.

Excel2 projects
Sales Executive Performance Dashboard141 executives across 8 regions, every view driven by one slicer

Five days of sales against target, built as linked pivot tables and charts that all re-cut together from a single region slicer.

The average target hit rate is 55.2%, with individuals running from 77.8% down to 28.6%.

What I'd doWhen half the floor misses the number, the target usually deserves scrutiny before the people do. Check how it was set, then coach against the spread rather than the average.

Bakery Sales Analysis700 orders over 16 months, with pivot tables and a forecast

Excel functions, pivot tables and a demand forecast across product performance, profitability and seasonal demand.

One customer is 32% of revenue, and the top two together are 57% of it.

What I'd doTreat this as concentration risk, not a success story. Protect those two accounts and grow the other three before one departure takes a third of the business.

Python4 projects
Black Friday Sales Analysis537,577 transactions explored in Pandas

Gender, age, marital status, occupation and city category tested against what people actually spend.

Unmarried men aged 26 to 35 are the largest segment in almost every cut, and men account for roughly 77% of total purchase value.

What I'd doStock and staff for that segment, then target with occupation rather than gender, since occupation separates customers by both spend and the variety of products they buy.

GDP AnalysisWorld Bank data, 1960 to 2016, with interactive Plotly charts

A growth metric derived from the raw figures across 256 countries and regions, plus a reusable function for comparing any set of countries.

Only 120 of the 256 have complete coverage across the period, and the sparse ones throw out wildly overstated growth rates.

What I'd doFilter to complete-coverage countries before ranking growth. Otherwise the leaderboard is an artefact of missing data rather than a finding.

Sugarcane Production EDAGlobal production by country and continent

Production volume, land use and yield per hectare, compared across countries and continents.

Production tracks acreage almost perfectly, a correlation of 0.998, while yield per hectare barely relates to total output at 0.13.

What I'd doIf the goal is total volume, land is the lever. Yield leaders like Guatemala are the interesting case for efficiency programmes, not for output targets.

Heart Disease Visualisation Techniques918 patients, each chart type chosen for the question it answers

Distributions, violin plots, a correlation heatmap and a pairplot over the UCI heart disease dataset.

172 of the 918 cholesterol readings are recorded as zero, which is missing data rather than a real measurement.

What I'd doFlag it before anyone models on this data. Treating those zeros as real readings would drag every cholesterol conclusion downwards.

Skills

Skills

The tools, and the projects on this page where each one did real work.

Python

Customer Shopping Behaviour, Black Friday, GDP Analysis, Sugarcane Production, Heart Disease. Pandas for cleaning and reshaping, Matplotlib, Seaborn and Plotly for the charts.

SQL

Customer Shopping Behaviour in PostgreSQL, Sales and Revenue and RFM Segmentation in MySQL. Joins, CTEs, Window Functions, NTILE and reusable views.

Excel

Bakery Sales, Sales Executive Performance Dashboard, and the Excel workbook in the capstone. PivotTables, Slicers, VLOOKUP/XLOOKUP and Power Query.

Power BI

The Customer Shopping Behaviour dashboard, built on a PostgreSQL table with slicers for subscription, gender, category and shipping.

Tableau

The Superstore dashboard, live on Tableau Public with year, state and category filters.

Working with Data

Data Cleaning and Preprocessing, Exploratory Data Analysis, Hypothesis Testing, Customer Segmentation (RFM), Data Storytelling.

Libraries

Pandas, NumPy, Scikit-learn, Matplotlib, Seaborn, Plotly.

Environment

Jupyter Notebook, PostgreSQL, MySQL, Git and GitHub, Jira, Google Sheets.

From the Day Job

SAP Analytics Cloud, SAP BTP, CPI and PI/PO Integration, ARIMA Time-Series Forecasting.

Experience

Experience
Aug – Oct 2025

SAP Technical Intern

Mygo Consulting, Naperville, IL

Built dashboards and analytical stories in SAP Analytics Cloud during hands-on training on SAP Business Technology Platform, and documented system behaviour, data flows and configuration workflows for the consultants I worked under.

Oct 2022 – Jun 2023

Associate Consultant, SAP Cloud Platform Integration

NTT DATA Business Solutions, Hyderabad, India

Cut data integration error rates by around 25% by tracing and fixing pipeline failures between cloud and on-premise systems, and reduced reprocessing and manual fixes by around 15% by tuning interfaces and message mappings. Unglamorous work, and it's where I learned what bad data costs everyone downstream.

Mar – Jun 2022

Machine Learning Intern

NTT DATA Business Solutions, Hyderabad, India

Forecast support ticket volume with 85% accuracy using an ARIMA model in Python, then turned the output into visual reports that fed staffing and capacity planning decisions.

Education

Education
Graduated May 2025

MS, Computer Science

University of Georgia, Athens, GA

Coursework in algorithms, database design, data mining, deep learning and distributed computing systems.

Certifications

Certifications
  • Certified Data Analyst AssociateDatabricks
  • Data Analysis with PythonfreeCodeCamp
  • Data Analysis in Tableau DesktopSalesforce Trailhead
  • Introduction to Transact-SQLMicrosoft

Contact

If something here lines up with a problem you're working on, I'd like to hear about it.

Based in Austin, Texas, and open to relocating. Entry-level data analyst roles, any industry.